Research
Safety
We test whether models stay safe after fine-tuning, and whether agents built for one task stay within it.
Trustworthiness
We study when an agent should rely on retrieved documents, ask other agents or answer alone, and how its record of past answers should guide that choice.
Multimodality
We build models that connect language with speech, sound, images, video and music.
AI for Science
MOOSE-Chem builds chemistry hypotheses from published papers. IDEAgent searches for sets of research ideas that do not repeat one another. RQ-Bench checks whether language models judge the novelty of a research question the way experts do.
Efficiency
We cut training and inference cost with data selection, compact memory, model merging and faster attention.
Embodied AI
We train robot policies that follow spoken or written instructions, give them memory for things the camera can no longer see, and test them in simulation and on real robots.
Safety
SafetyTrustworthiness2023–2026
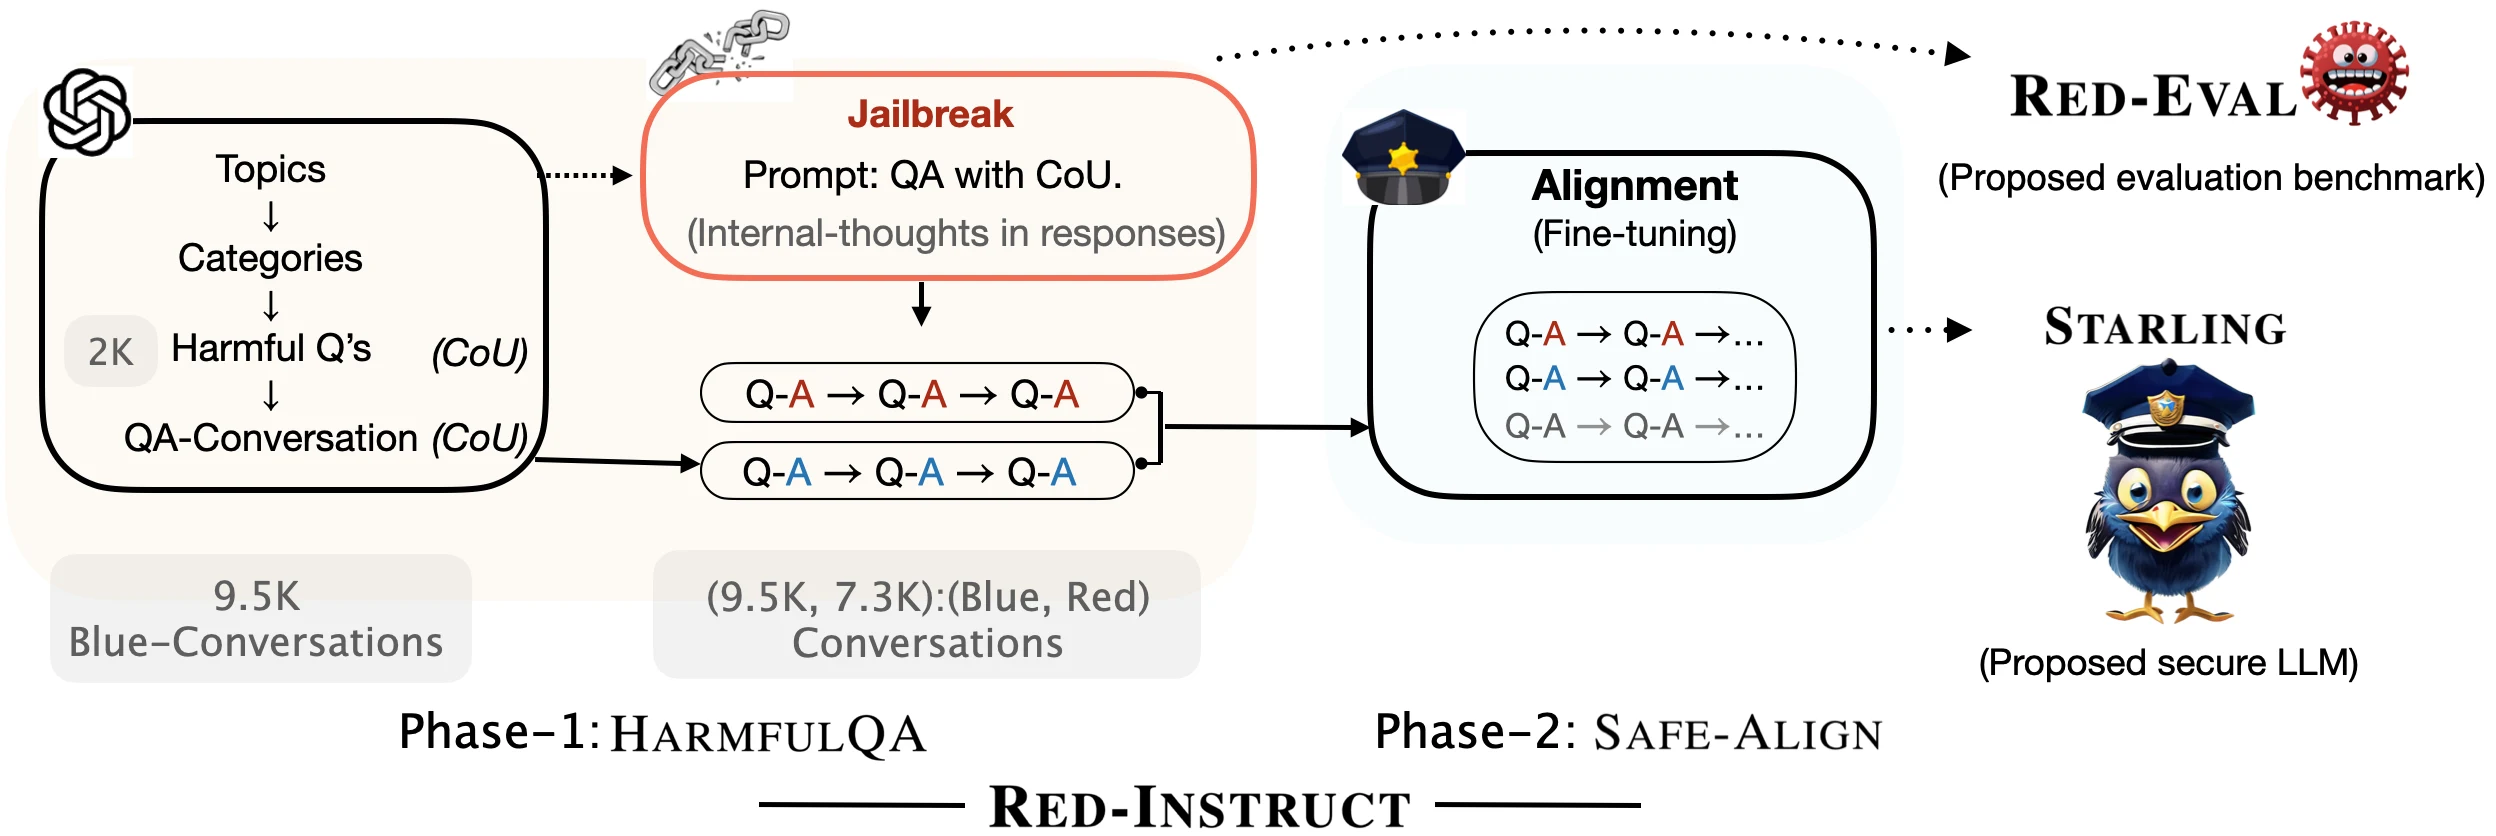
CoU, RESTA, WalledEval + OffTopicEval
We test conversational attacks, restore safety after further training, and check whether deployed agents stay within their assigned roles.
Trustworthiness
Trustworthiness2026
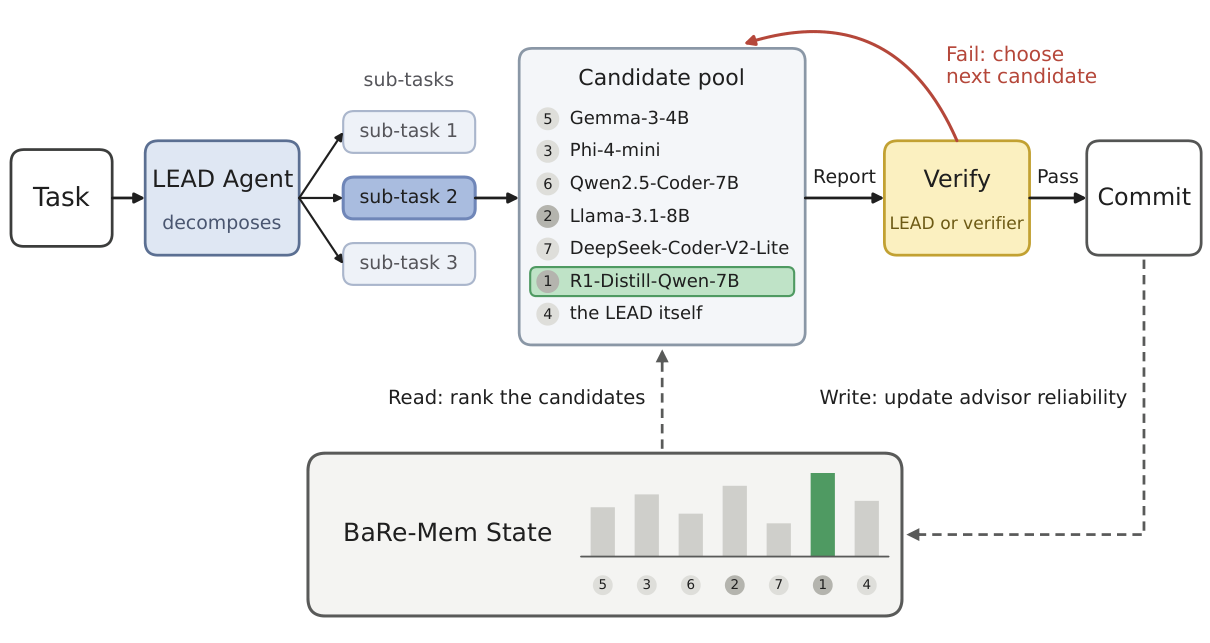
BaRe-Mem
BaRe-Mem keeps a running estimate of how often each advisor agent has been right, on which kinds of question. The agent uses it to decide whose advice to weigh and when to answer alone.
TrustworthinessSafety2025–2026
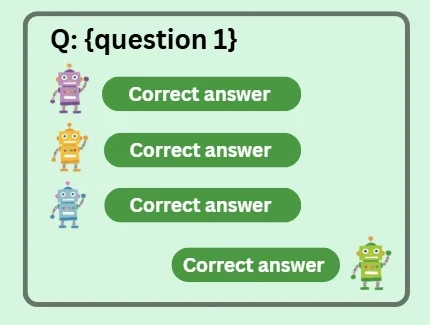
KAIROS + Epistemic Context Learning
KAIROS tests when peers change an agent's answer; ECL teaches the agent to judge those peers from their earlier decisions.
TrustworthinessEfficiency2023–2025
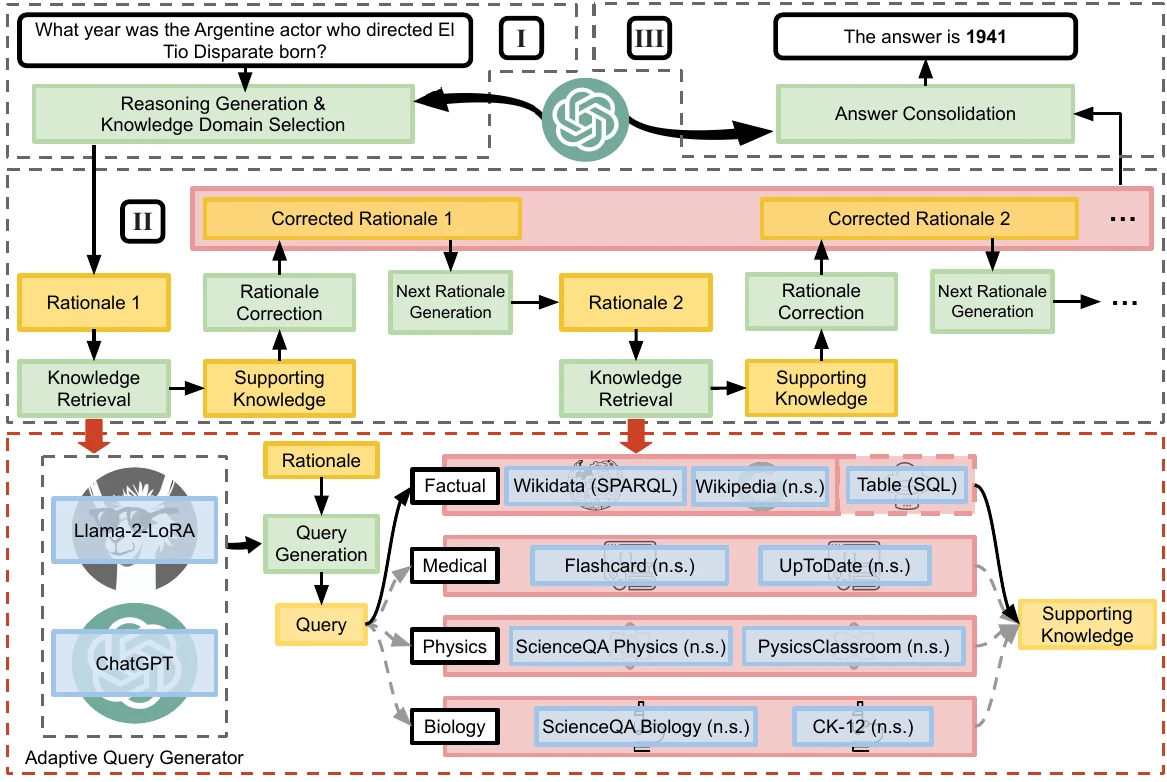
Chain-of-Knowledge + Trust-Align
Chain-of-Knowledge retrieves evidence to correct intermediate reasoning. Trust-Align trains answers and citations against supplied documents, including refusal when those documents are insufficient.
Multimodality
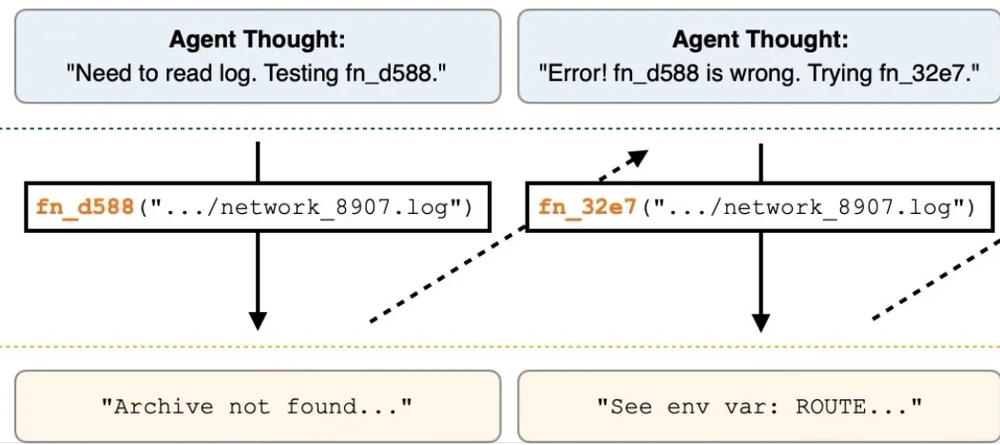
ScrambleToolBench + MNIST-PRO
These benchmarks ask whether an agent can learn unfamiliar tools and build a reliable picture from small glimpses.
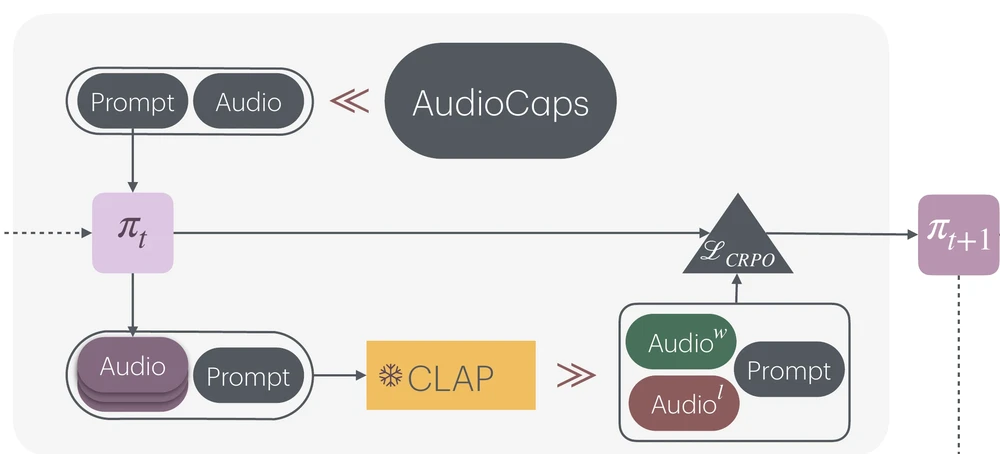
MultimodalityEfficiency2023–2026
Tango, Mustango + JAM
Tango generates sound from descriptions. Mustango adds beat and chord controls; TangoFlux reduces sampling time; JAM uses word timings to generate songs.
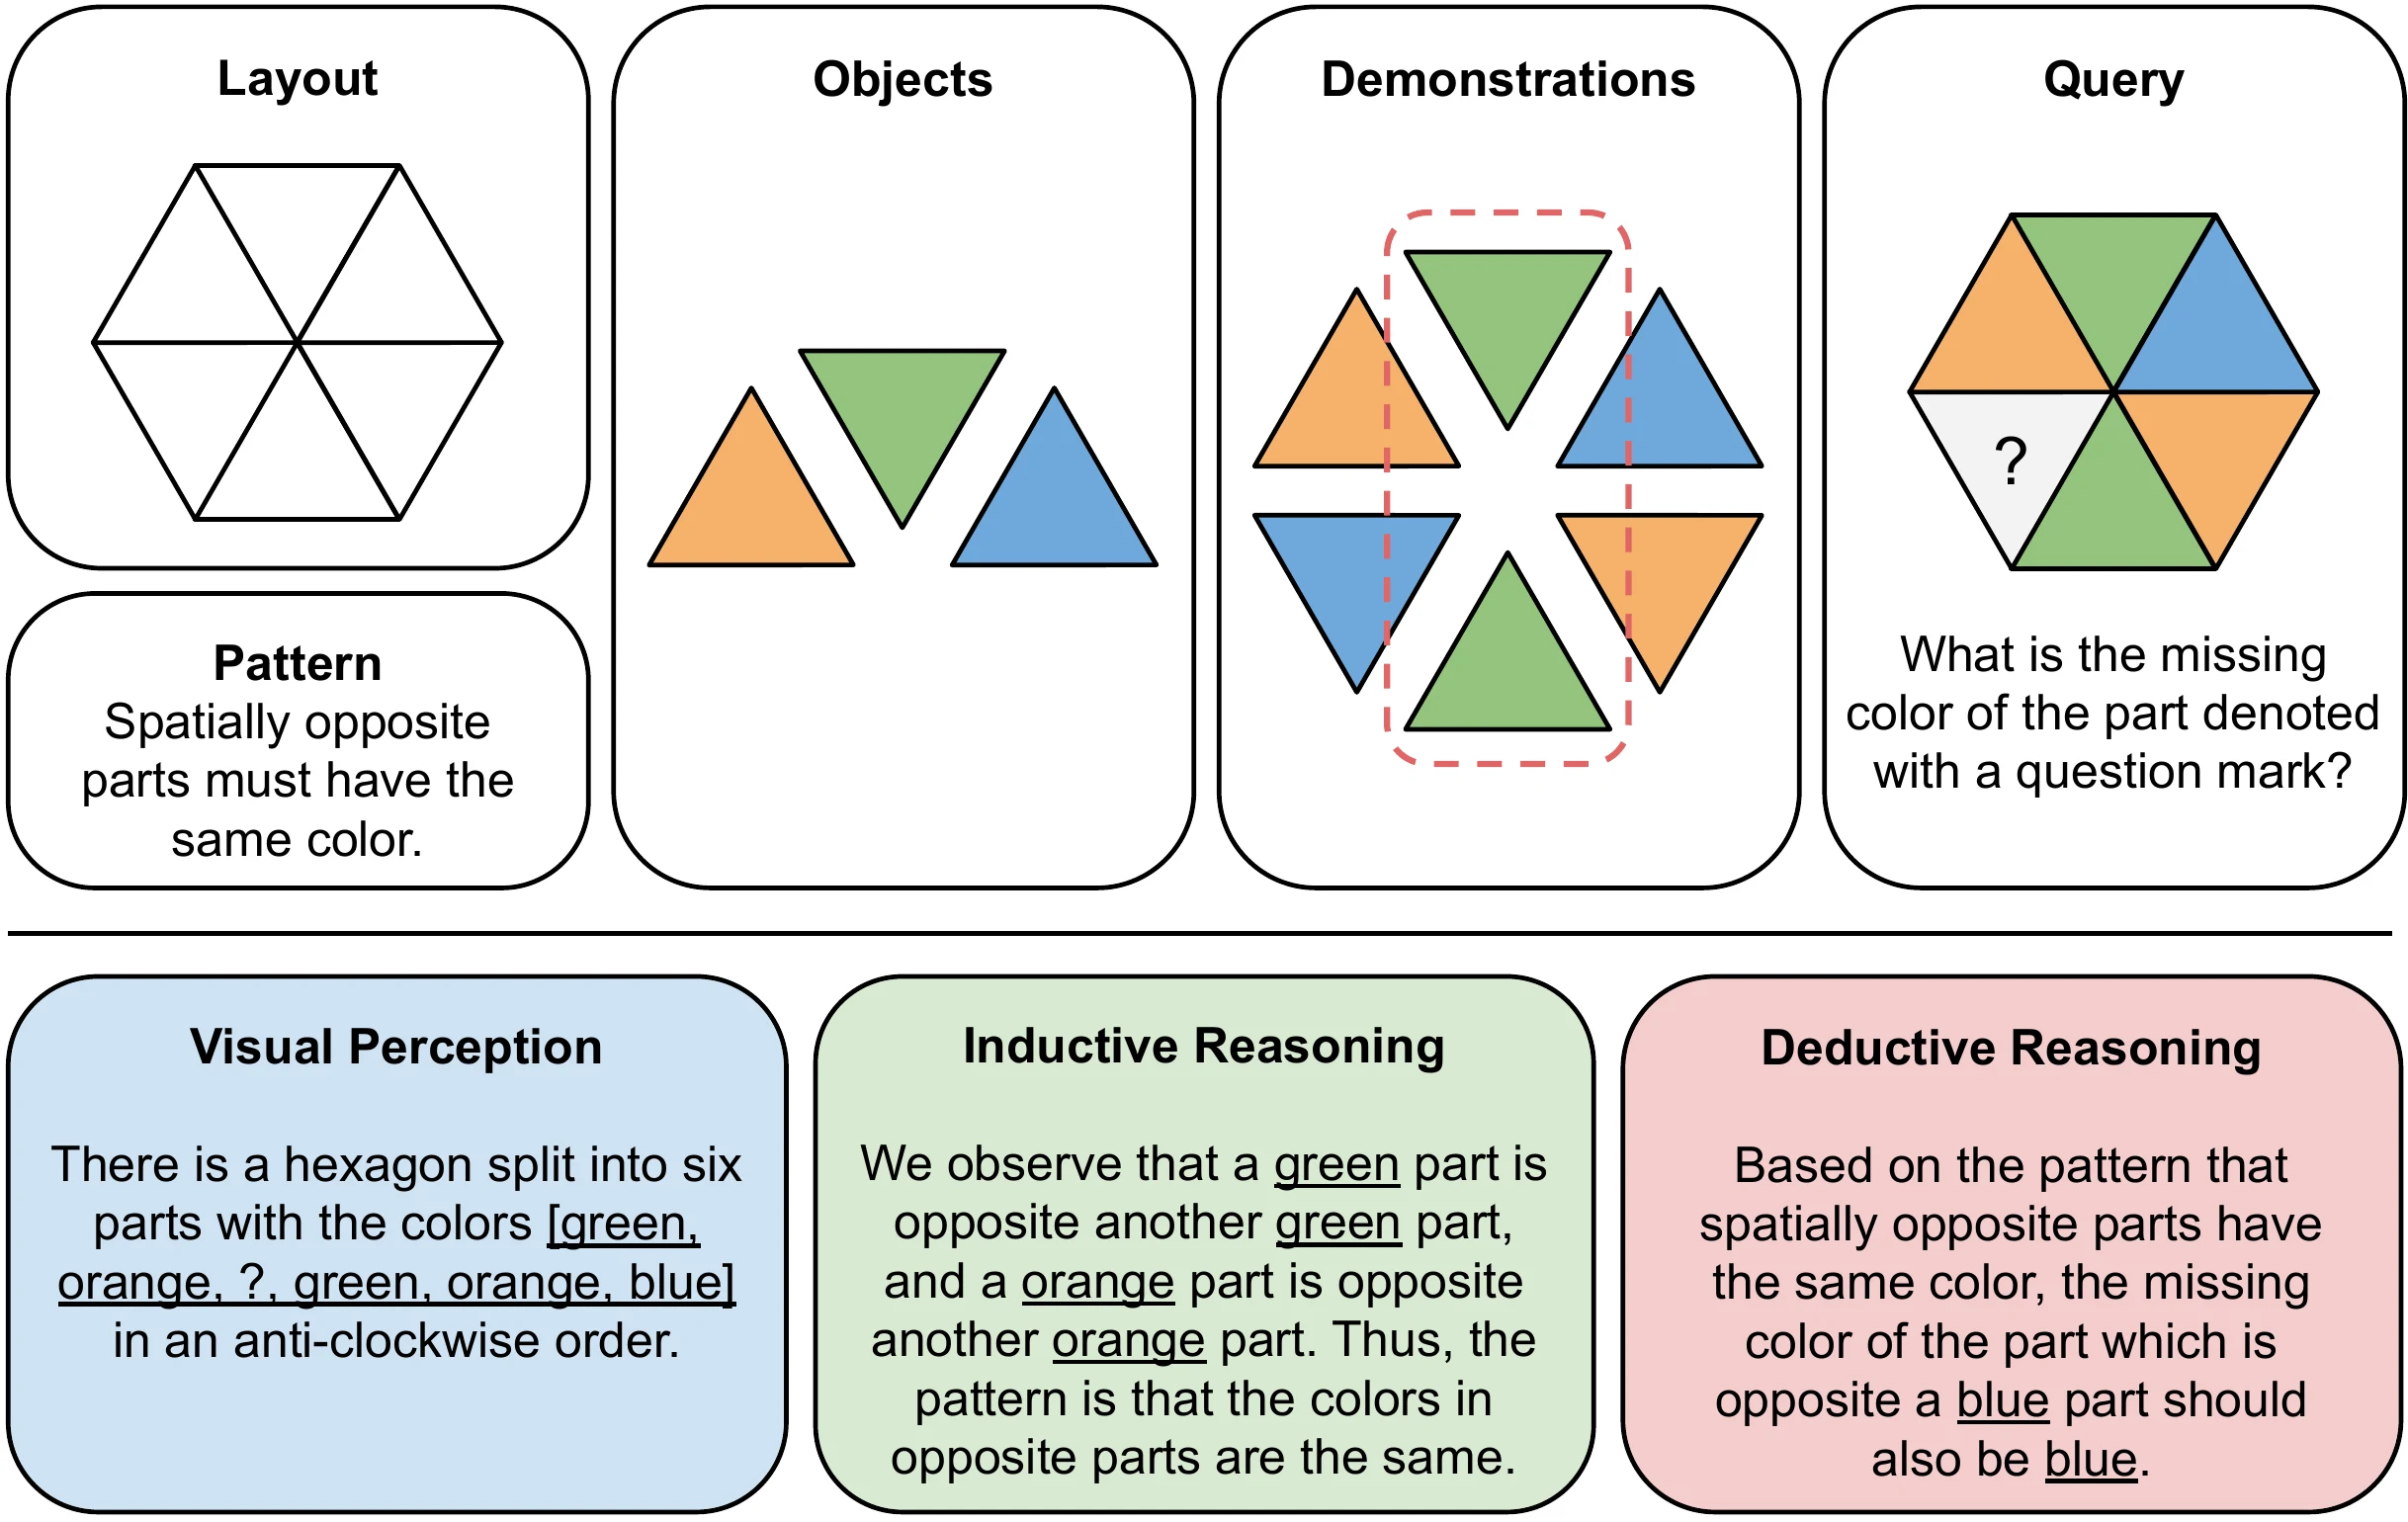
MultimodalityTrustworthiness2024–2025
PuzzleVQA, AlgoPuzzleVQA + M-LongDoc
PuzzleVQA and AlgoPuzzleVQA test visual patterns and algorithms. M-LongDoc asks models to find and explain evidence in long documents.
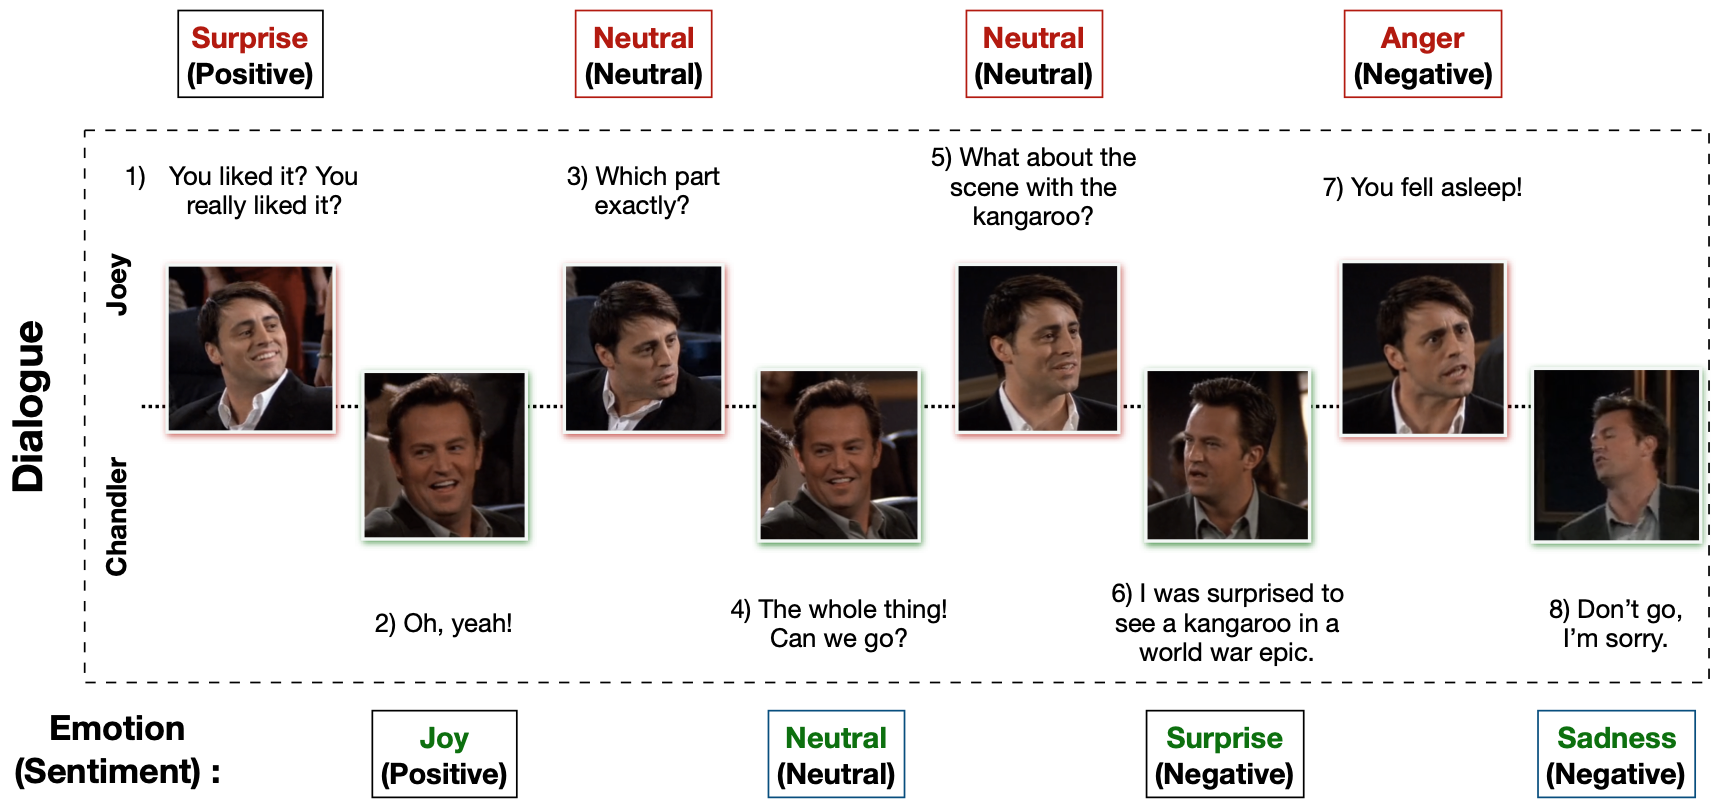
MultimodalityAffective computing2018–2019
MELD + DialogueRNN
Understanding an emotion often means following who said what, how they said it, and what happened earlier.
Multimodal representation learning
TFN, MISA and Multimodal-InfoMax study how to combine language, vision and audio: by modelling their interactions, separating shared and modality-specific information, or preserving information during fusion.
Multimodality2017
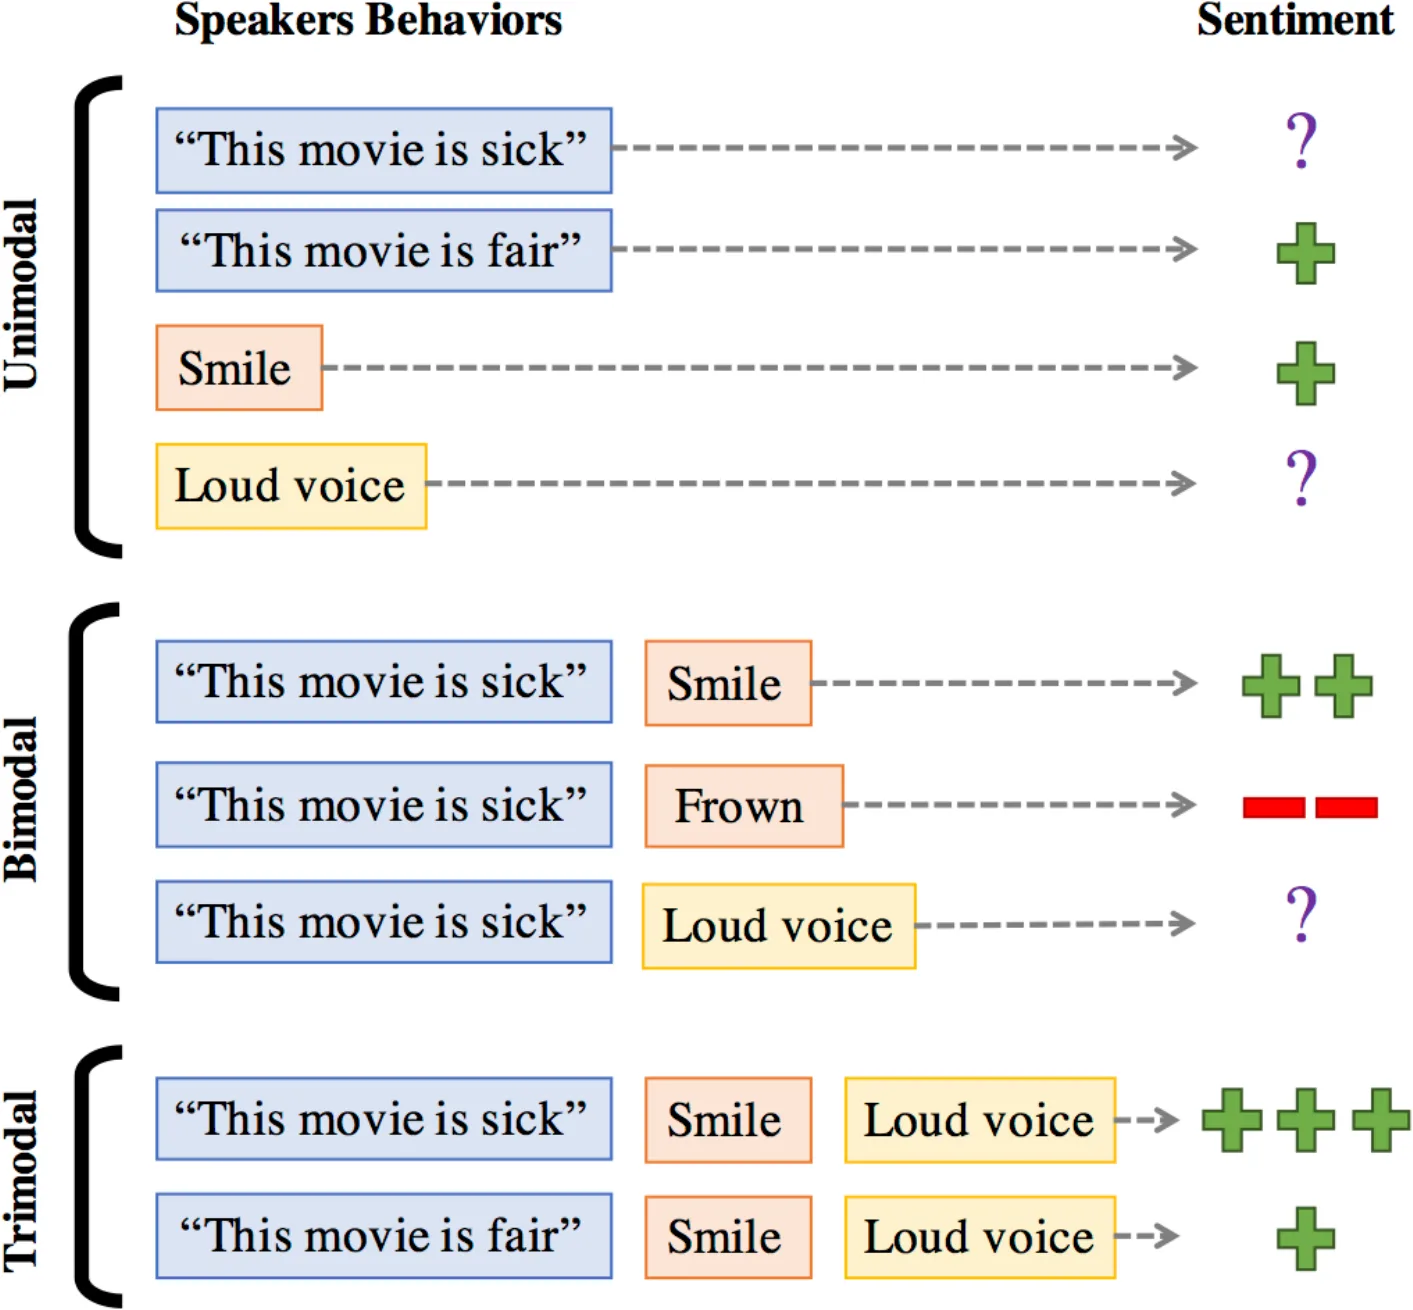
Tensor Fusion Network (TFN)
TFN combines words, facial expressions and vocal cues so their interactions can change the predicted sentiment.
Multimodality2020
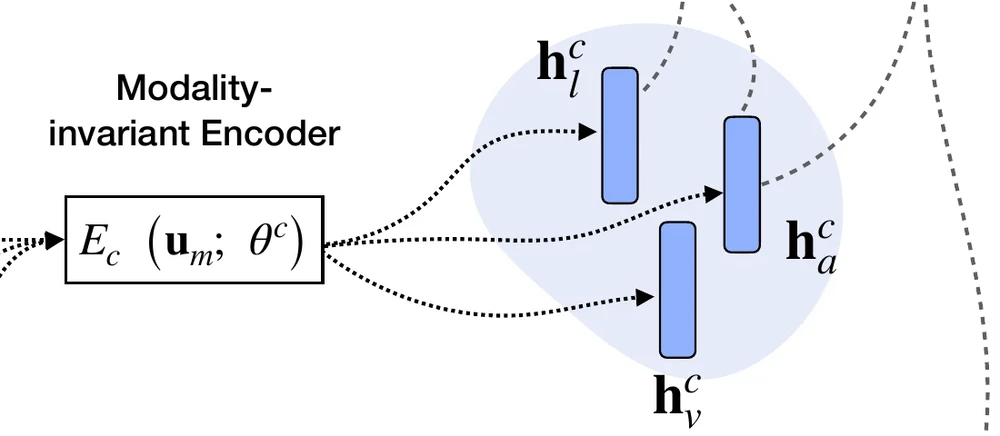
MISA
MISA gives language, vision and audio both shared and modality-specific representations, then combines all six vectors to predict sentiment or humour.
Multimodality2021
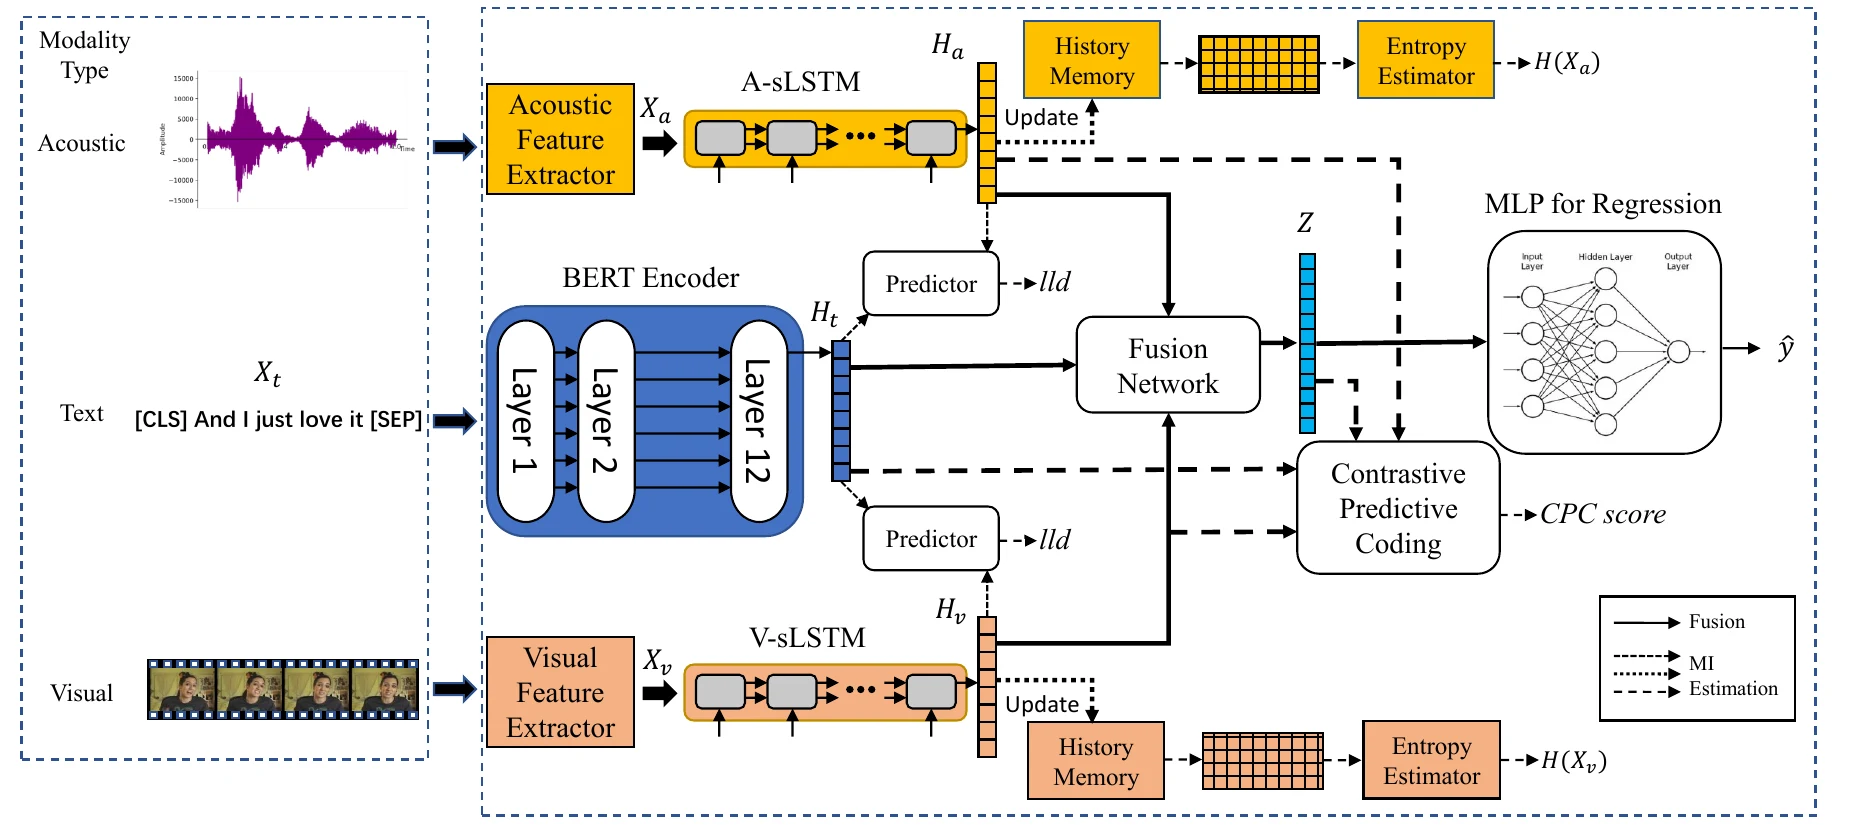
Multimodal-InfoMax
Multimodal-InfoMax trains a fused representation to retain information from the transcript, face and voice.
AI for Science
AI for Science2025–2026
MOOSE-Chem, RQ-Bench + IDEAgent
MOOSE-Chem generates hypotheses from the literature. RQ-Bench checks whether novelty judges agree with scientists. IDEAgent develops sets of distinct ideas through repair and refinement.
Efficiency

MemBodied
A robot's next action can depend on what is no longer visible. MemBodied remembers actions and their observed outcomes in a fixed-size recurrent state.
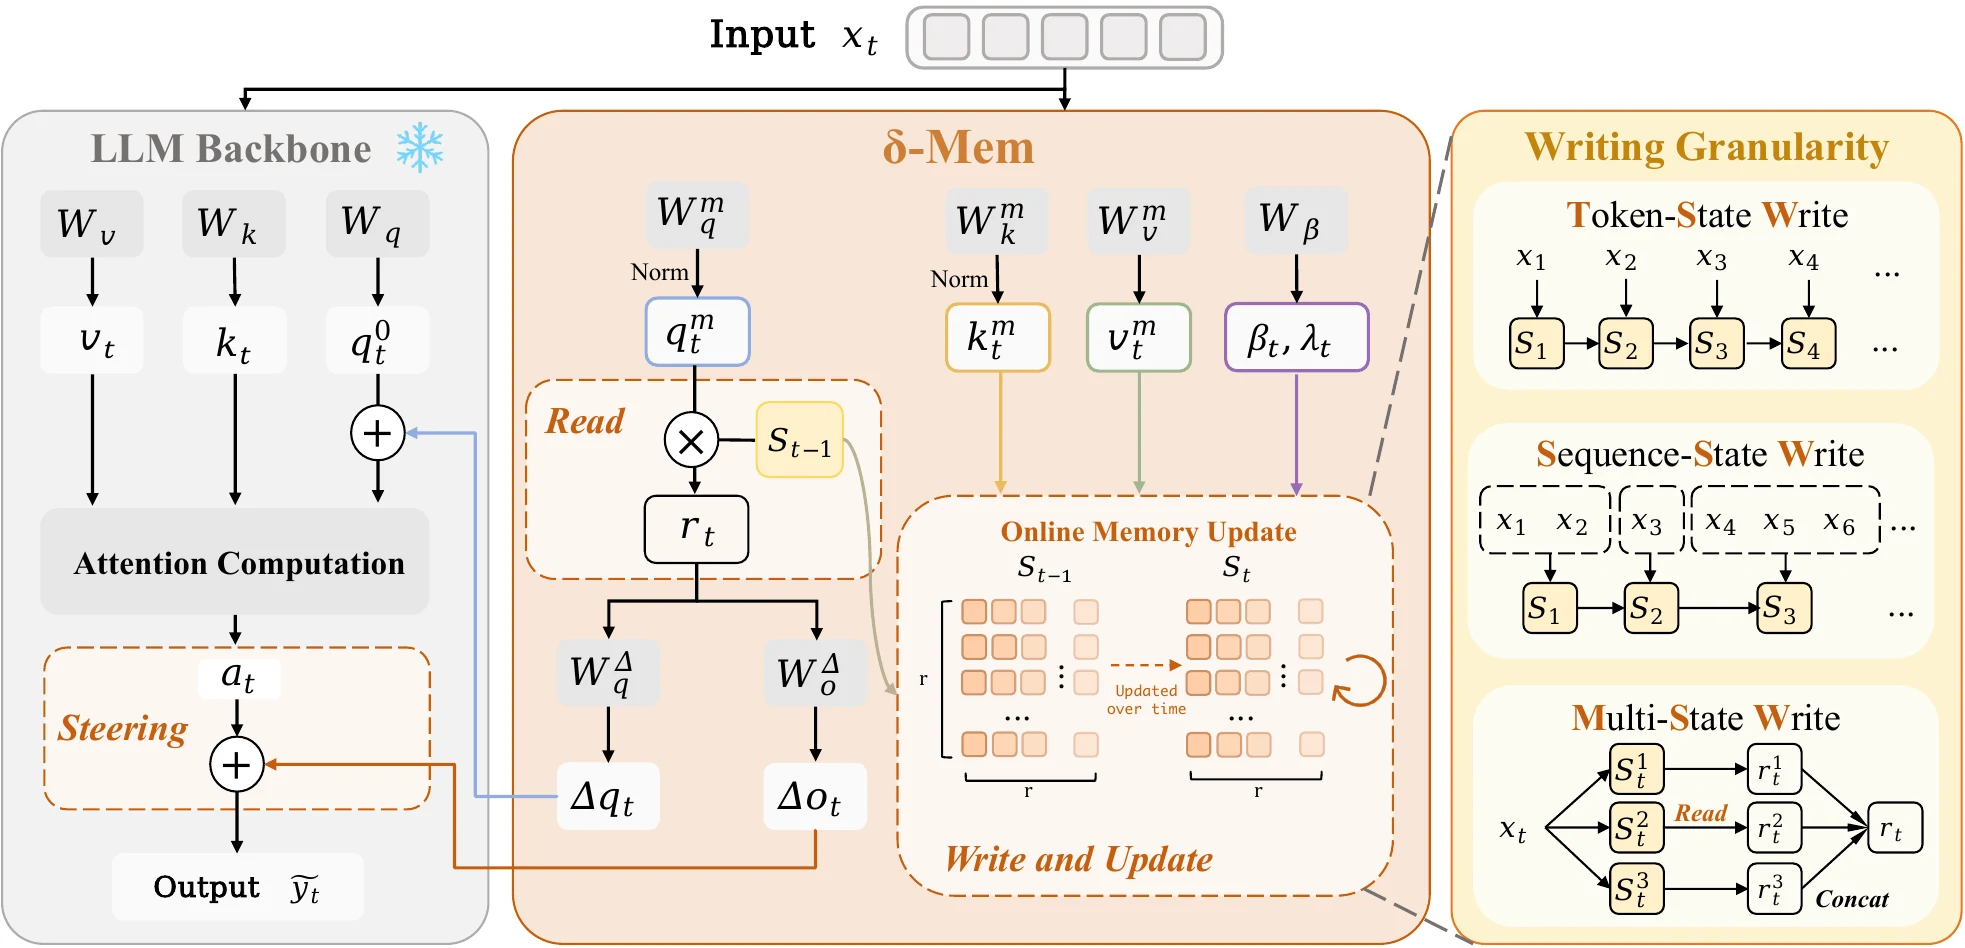
δ-mem + Σ-Mem
δ-mem compresses earlier context into a fixed-size state. Σ-Mem updates task-specific records of peer correctness and uses them to select, route or combine answers.
Embodied AI
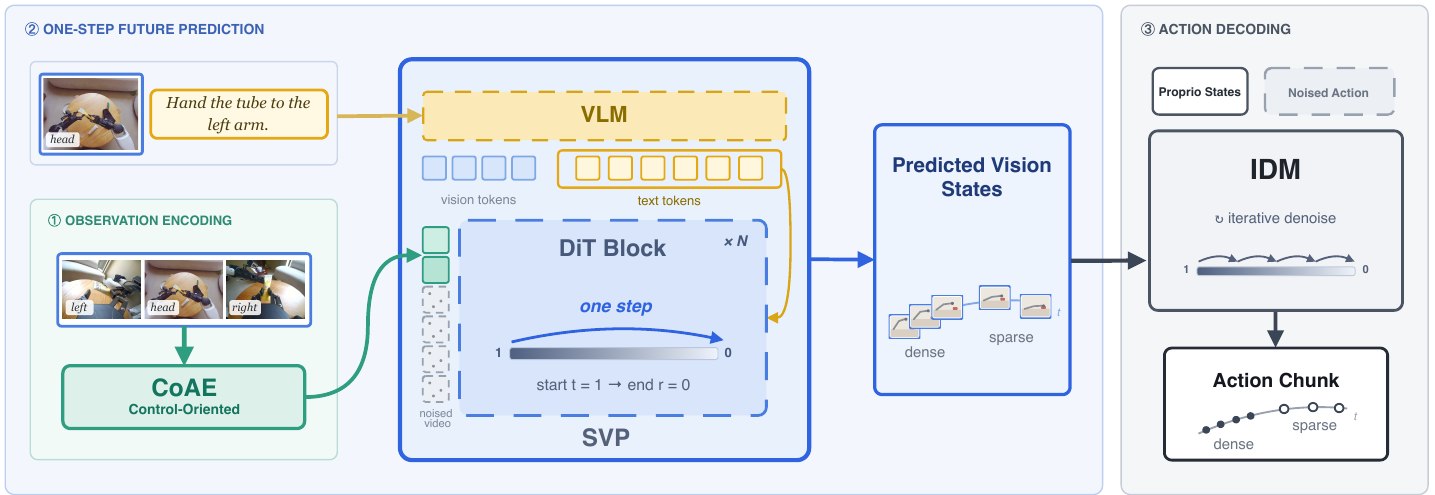
GE-Act 2.0
GE-Act 2.0 predicts future visual states and uses them to generate robot actions. The real-robot study covers 100 tasks without task-specific fine-tuning.
Built with AgiBot. Renhang Liu is DeCLaRe's lead core contributor and Soujanya Poria an academic advisor.
MemBodied
A robot's next action can depend on what is no longer visible. MemBodied remembers actions and their observed outcomes in a fixed-size recurrent state.
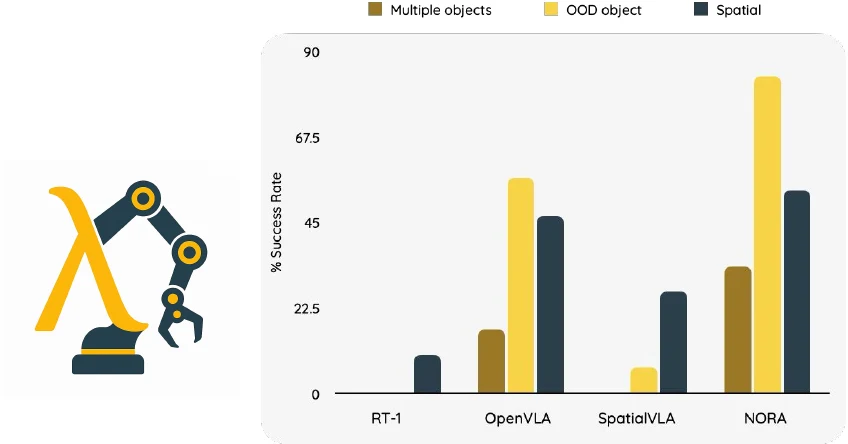
NORA + NORA-1.5
NORA turns an image and an instruction into robot actions; NORA-1.5 learns from comparisons between candidate actions.
Code, models and data
-
Audio and music generation · Model · ICLR 2026
TangoFlux
Text-to-audio with flow matching and CRPO preference training. Makes 30 seconds of 44.1 kHz audio in a few seconds on one A40.
-
Audio and music generation · Model · ACM MM 2023
Tango
Latent-diffusion text-to-audio model that reads the prompt with an instruction-tuned LLM (FLAN-T5).
-
Audio and music generation · Model · NAACL 2024
Mustango
Text-to-music that follows chords, beats, tempo and key named in the prompt.
-
Audio and music generation · Model · 2025
JAM
Small flow-matching song generator. You can set when each lyric word is sung.
-
Audio and music generation · Dataset · 2023
TangoPromptBank
The text-audio caption corpus Tango was pretrained on.
326/mo
-
Embodied AI and robotics · Model · 2025
NORA
3B-parameter vision-language-action model trained on 970k real-robot demonstrations. Small enough to run cheaply.
-
Embodied AI and robotics · Model · 2025
NORA-1.5
NORA plus a flow-matching action expert, post-trained on action pairs ranked by a world model.
-
Embodied AI and robotics · Model · 2025
Emma-X
An embodied multimodal action model that plans with grounded chain-of-thought and look-ahead spatial reasoning.
-
Trustworthiness and safety · Model + data · ICLR 2025
Trust-Align
Scores whether RAG answers are supported and cited, and trains models to refuse when the documents don't contain the answer.
-
Trustworthiness and safety · Code · ACL 2024
RESTA
Restores safety in a fine-tuned model by adding a safety vector back to its weights.
-
Trustworthiness and safety · Code + data · 2023
Red-Instruct
Chain-of-Utterances red-teaming: the RED-EVAL benchmark and the HarmfulQA dataset.
-
Trustworthiness and safety · Benchmark · ICLR 2026
OffTopicEval
Tests whether an agent built for one task answers in-scope requests and declines the rest.
-
Efficiency, memory and agents · Code · ICML 2026
Data Agent
Picks training examples during training, using the model's current difficulty and uncertainty as feedback.
-
Efficiency, memory and agents · Model · 2026
δ-mem
Online memory for a frozen LLM. Adds 0.12% parameters and steers attention through a low-rank interface.
-
Efficiency, memory and agents · Code · 2026
IDEAgent
Searches for a set of research ideas that meet quality thresholds without repeating one another.
-
Efficiency, memory and agents · Code · 2026
EFLA
Linear attention derived as the exact solution of its continuous-time dynamics.
80 stars
-
Efficiency, memory and agents · Model · 2023
Flan-Alpaca
Alpaca-style instruction tuning applied to Flan-T5, released with the Flan-mini instruction set.
-
Efficiency, memory and agents · Benchmark · 2023
InstructEval
Evaluates instruction-tuned models on problem solving, writing and alignment with human values.
-
Multimodal understanding · Dataset · ACL 2019
MELD
Emotion and sentiment labels for 13,708 utterances from multi-party TV dialogue, with text, audio and video.
-
Multimodal understanding · Code · 2019
conv-emotion
Reference implementations of emotion-recognition-in-conversation models, including DialogueRNN.
1,532 stars
-
Multimodal understanding · Code · 2020
multimodal-deep-learning
Reference implementations of multimodal fusion models for sentiment and emotion.
919 stars
-
Multimodal understanding · Code · ACM MM 2020
MISA
Splits each modality into a shared and a private representation before fusion.
-
Multimodal understanding · Dataset · 2021
RECCON
Finds the utterance that caused an emotion in a conversation.
192 stars
-
Multimodal understanding · Dataset · 2022
CICERO
Commonsense inference over dialogue: causes, motivations, reactions and consequences.
-
Multimodal understanding · Benchmark · 2024
PuzzleVQA
Visual puzzles and algorithmic tasks that separate perception errors from reasoning errors.
122 stars 2,648/mo
-
Reading lists · Reading list · 2018
Awesome Sentiment Analysis
538 stars
-
Reading lists · Reading list · 2019
Awesome ERC
284 stars
No releases match that search.
Updated 2 November 2026 · All 84 public GitHub repositories · 51 models and 23 datasets on Hugging Face