Trustworthiness · 2026
← Trustworthiness researchBaRe-Mem
When should an agent trust its peers, and when should it answer alone? BaRe-Mem uses verified experience to estimate reliability and guide both decisions.
Whose answer deserves attention?
A fluent answer is not necessarily a correct one. In a group of agents, competence varies with the question, and agreement can reinforce a shared mistake. BaRe-Mem—Bayesian Reliability Memory for Robust and Adaptive Agent Consultation—uses verified interaction history to estimate how reliable each candidate answer is for the current problem.
The same record supports two decisions: how much the agent should attend to each peer’s answer, and whether consulting those peers is preferable to using its own answer.
A contextual record of correctness
Each candidate is represented by its source identity, a representation of the question and a representation of its answer. A Bayesian linear regression model connects this address to verified correctness. The central agent’s independent answer is recorded alongside its peers, giving the memory a comparable estimate of autonomous ability.
After verification, rank-one updates revise the posterior mean and covariance without a new matrix inversion. At decision time, both the estimated correctness and its uncertainty contribute to the reliability score. Sparse evidence therefore does not warrant the same confidence as a well-supported history.
Make reliability affect reasoning
The memory’s estimates directly modify attention over peer responses. An additive attention bias leaves the most trusted candidate’s logits unchanged and reduces the weight of less trusted answers relative to it. The language model stays frozen; reliability is updated in the external Bayesian state.
This relative weighting answers whose evidence to emphasize. It cannot, by itself, establish that any of the available advice is useful.
Know when to answer alone
BaRe-Mem also learns a small model of consultation ability from verified outcomes. It relates trust in the peer evidence to the central model’s ability to read good evidence and its susceptibility to bad evidence. For each question, the method compares estimated consultation accuracy with estimated autonomous accuracy and selects between the two answers.
This decision relies on historical estimates, rather than access to the current answer’s correctness. The formulation assumes verified feedback for candidate answers and for the consultation outcome, including when the autonomous answer is selected. That feedback is a substantive requirement of the method.
Robustness to misleading advice
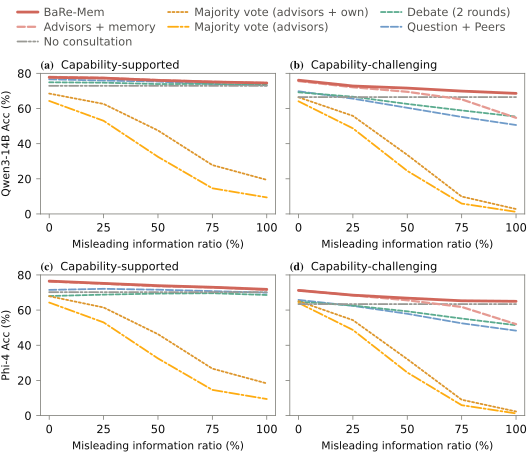
The experiments compare autonomous reasoning, prompted consultation, debate, majority voting and reliability-guided consultation under controlled misleading-advice ratios from 0% to 100%. The evaluation covers GSM8K, SQuAD and APPS, alongside a more heterogeneous suite of PIQA, MMLU, OpenBookQA, SciQ, BBH and SuperGLUE.
In the paper’s capability-challenging suite, Qwen3-14B with BaRe-Mem reaches 68.6% accuracy at 100% misleading advice, compared with 50.6% for question-plus-peers consultation and 66.5% for autonomous reasoning. Its consultation ratio falls from 90% at 0% misleading advice to 21% at 100%. For Phi-4 at 100%, the corresponding accuracies are 65.0%, 48.3% and 63.4%, with consultation selected on 18% of questions. These are controlled corruption experiments, rather than a guarantee against arbitrary misleading sources.
Route and replan an agent team
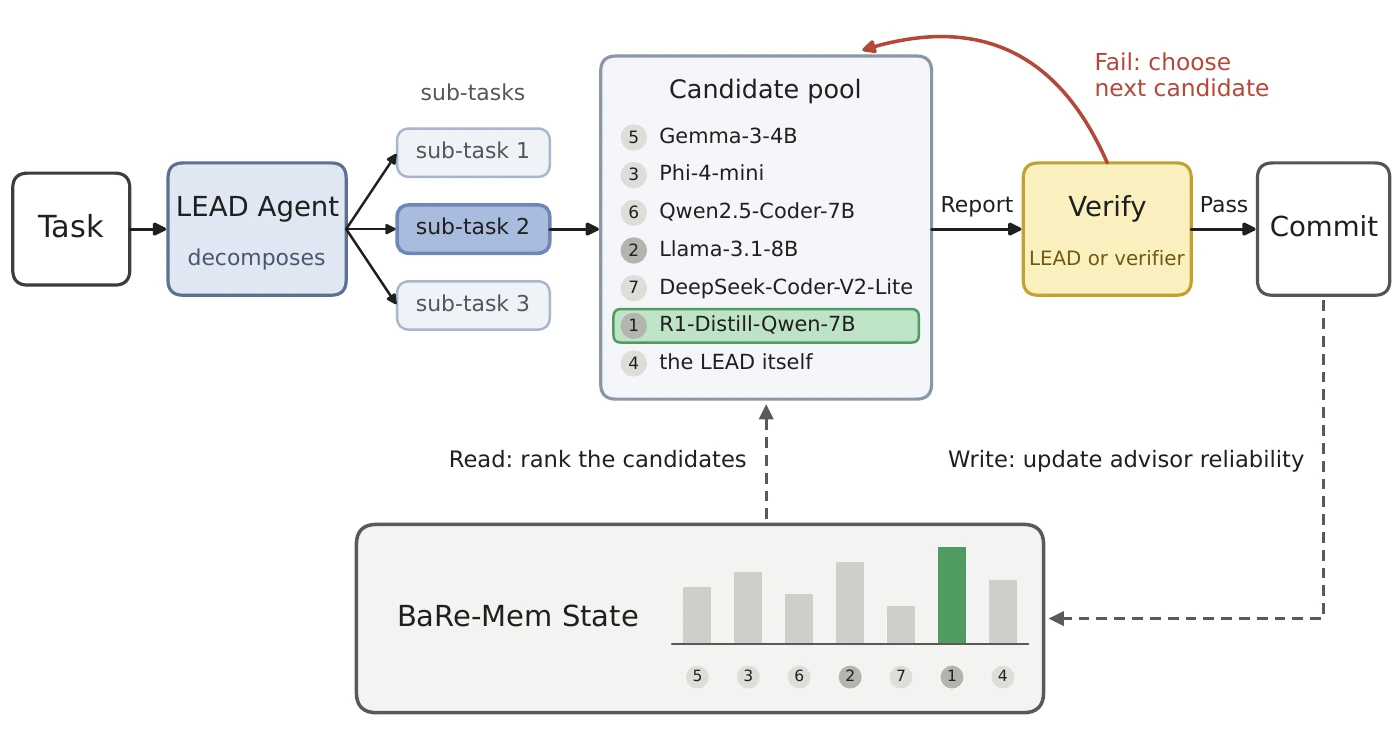
The agent-team study uses 2,417 MuSiQue tasks containing 6,404 sub-tasks. A lead agent assigns each sub-task to a worker and tries another worker when a returned report fails verification. Here, memory ranks workers before assignment, rather than only reweighting an existing set of answers.
The study compares random routing, routing by historical success counts and BaRe-Mem under no checking, lead-agent checking and exact dataset verification. It reports that BaRe-Mem finds capable workers with fewer calls; when all workers are tried, the routing strategies approach the same available-worker ceiling. The distinction between a model’s check and an exact evaluator matters when interpreting these results.
Two roles for persistent memory
MemBodied remembers actions and outcomes for robot control. BaRe-Mem remembers evidence about reliability for agent consultation. Together, they study how past experience should change a model’s next decision.
Paper, code and related research
2026 · Bayesian reliability memory
BaRe-Mem
The published manuscript, implementation and evaluation data for adaptive agent consultation.
2026 · online content and reliability memory
δ-mem and Σ-Mem
Related work on compact context memory and task-conditioned records of peer reliability.