Abstract
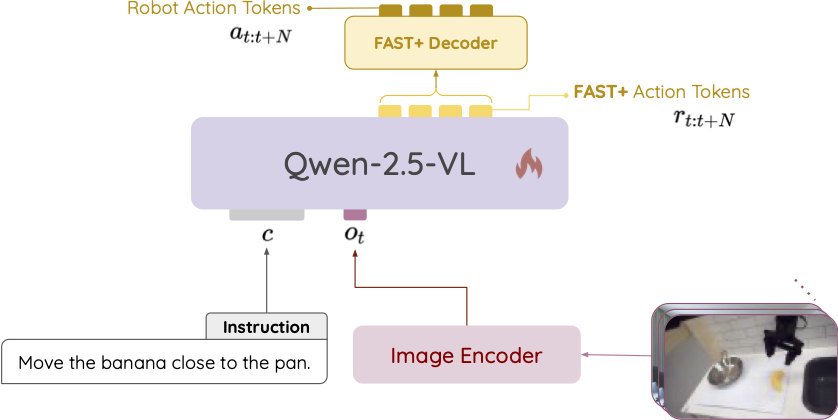
NORA is a 3B-parameter vision-language-action model based on Qwen2.5-VL-3B. It is trained on 970,000 real-world robot demonstrations and uses the FAST+ tokenizer to represent action sequences. The smaller backbone is intended to reduce the cost of fine-tuning and inference.
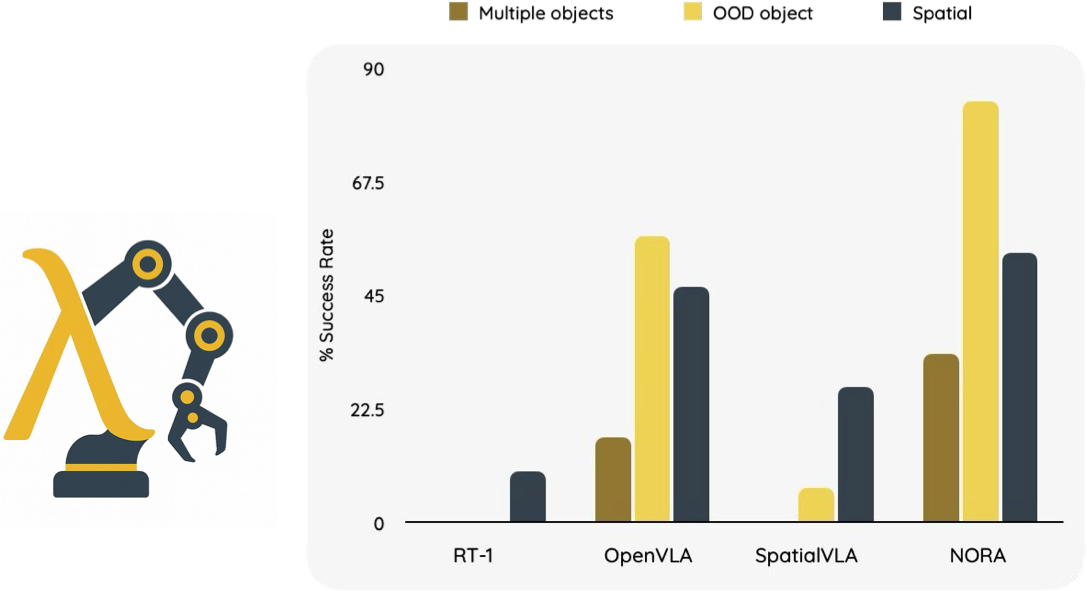
The paper evaluates NORA on robot manipulation and compares its task performance and computational cost with larger VLA models.
Model
Tasks with distractors
With object distraction: Put the pink toy in pot
With human distraction: Put the carrot in pot
With human + object distraction: Put the pink toy in pot
More robot demonstrations
Put the blue cube on the plate
Put the corn and carrot in pan
Put banana and carrot in pot
Move the banana close to the pan
Put carrot in the pot
Put the pink toy at the right corner
Put the carrot and hotdog in pot
Put the blue cube on the plate
Put banana in pot
Put the red bottle and the hamburger in the pan